International Baccalaureate · DP 2: Applications and Interpretation SL
Bivariate Statistics
I
Association between Two Variables
I.1
Bivariate Data
Recappreviously studied — click to reread
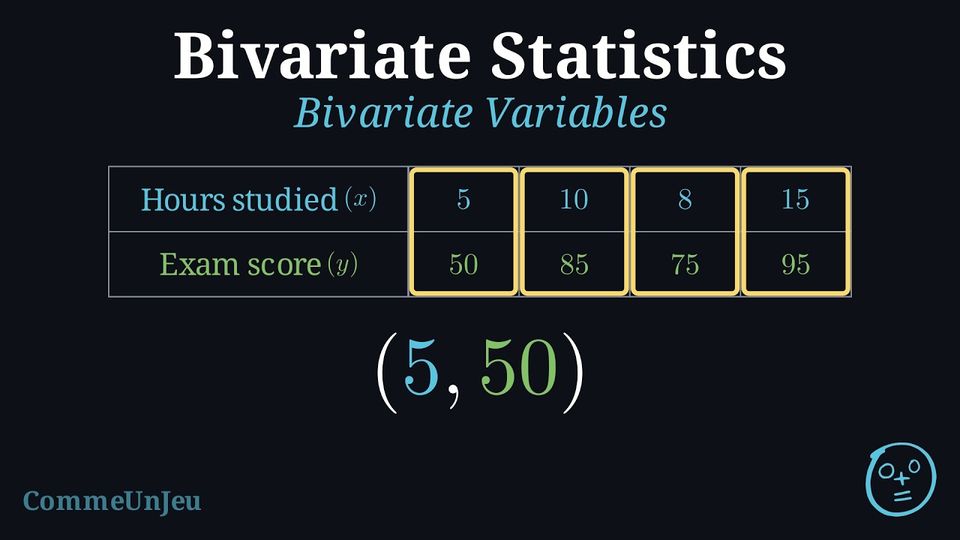
In univariate statistics, we analyse a single variable at a time. Bivariate statistics extends this analysis to explore the relationship between two variables. By examining pairs of data, we can investigate patterns, determine the nature and strength of their relationship, and use this relationship to make predictions. Bivariate statistics studies the relationship between two quantitative variables.
Definition — Bivariate Data
Bivariate data consists of pairs of values for two quantitative variables, recorded for each individual in a dataset. When one variable is studied as a possible explanation of the other, the pairs are written \((x, y)\), where: - \(x\) is the independent (or explanatory) variable.
- \(y\) is the dependent (or response) variable.
Example
A teacher records the hours each student studied (\(x\)) and their final exam score (\(y\)). | Hours Studied (\(x\)) | 5 | 10 | 8 | 15 |
| Exam Score (\(y\)) | 50 | 85 | 75 | 95 |
Skills to practice
- Identifying Explanatory and Response Variables
I.2
Scatter Diagrams
Recappreviously studied — click to reread
Definition — Scatter Plot
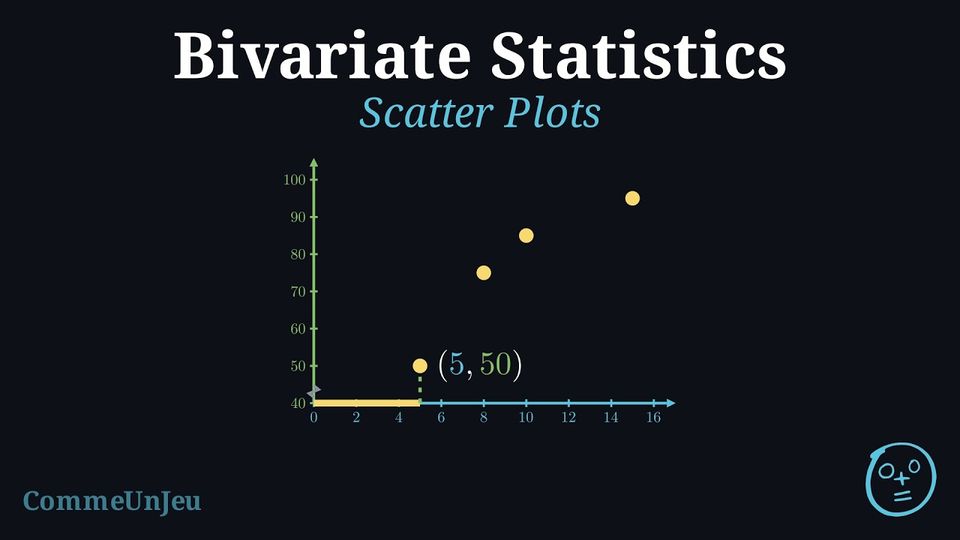
A scatter plot is a graph that displays bivariate data as a collection of points in the Cartesian plane. The independent (explanatory) variable is plotted on the horizontal axis (\(x\)-axis), and the dependent (response) variable is plotted on the vertical axis (\(y\)-axis).
A scatter plot is the primary tool for visually identifying a potential relationship, or correlation, between two quantitative variables.
Method — Constructing a Scatter Plot
- Identify Variables: Determine which variable is independent (\(x\)) and which is dependent (\(y\)).
- Set Up the Axes: Draw and label the horizontal axis for the \(x\)-variable and the vertical axis for the \(y\)-variable. Choose appropriate scales for both axes that cover the range of the data.
- Plot the Points: For each pair of (\(x, y\)) values in the dataset, plot a single point on the graph at the corresponding coordinates.
Example
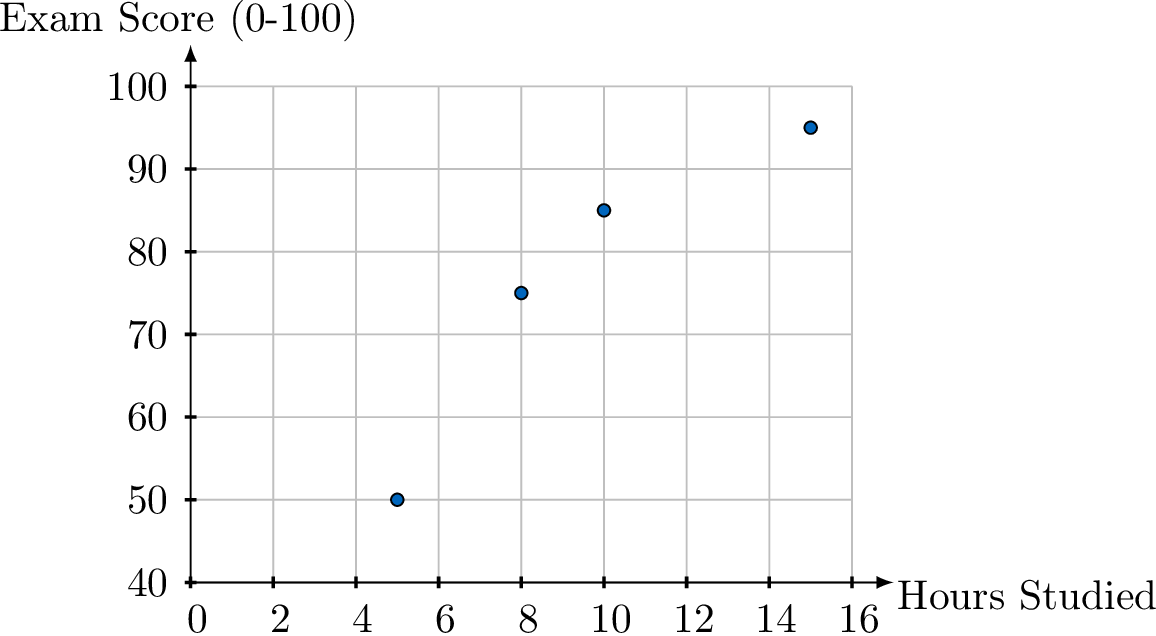
A teacher recorded the number of hours students studied and their corresponding exam scores. The data is shown below: | Hours Studied (\(x\)) | 5 | 10 | 8 | 15 |
| Exam Score (\(y\)) | 50 | 85 | 75 | 95 |
- Variables: “Hours Studied” is the independent variable (\(x\)) and “Exam Score” is the dependent variable (\(y\)).
- Axes: The \(x\)-axis is labelled “Hours Studied” and the \(y\)-axis “Exam Score”. The scales cover the ranges of the data.
- Plot Points: We plot the four coordinate pairs: (5, 50), (10, 85), (8, 75), and (15, 95).
Skills to practice
- Reading Scatter Diagrams
I.3
Describing a Correlation
Recappreviously studied — click to reread
Definition — Correlation
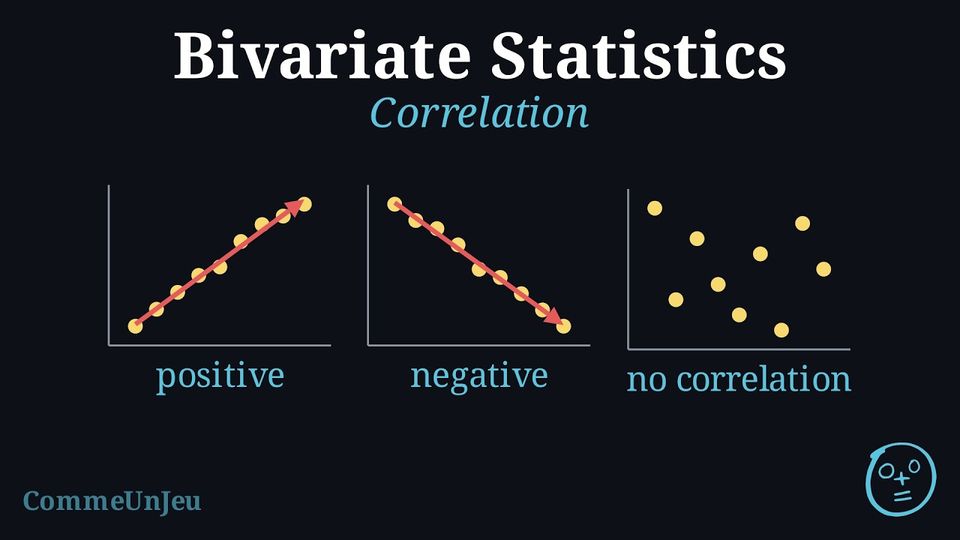
Correlation describes the nature of the relationship between two quantitative variables. Definition — Direction: Positive or Negative
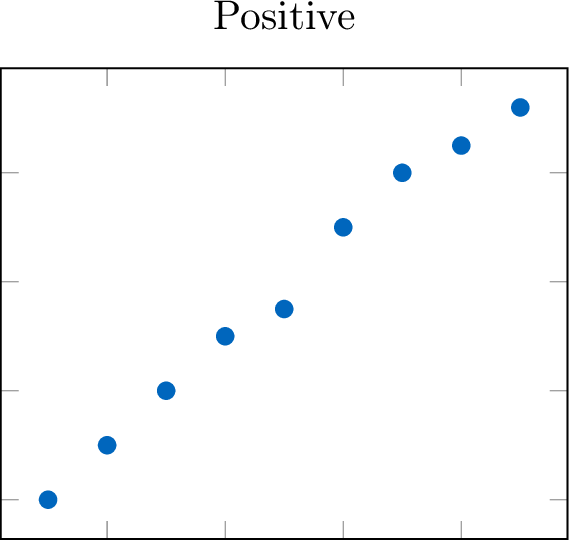
The direction describes the overall trend of the data. - Positive: As the independent variable (\(x\)) increases, the dependent variable (\(y\)) tends to increase. The points trend upward.
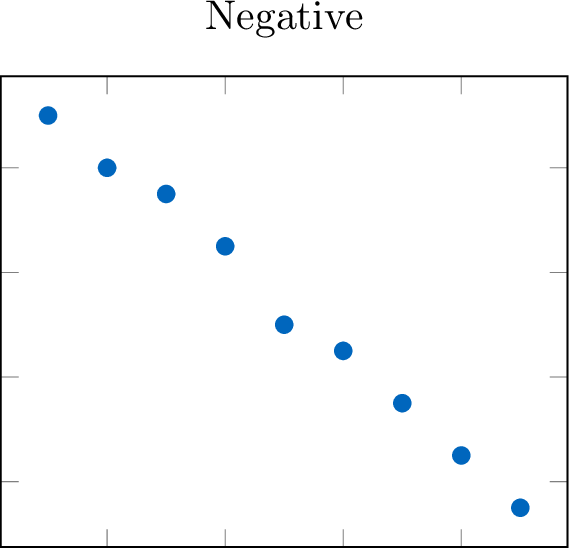
- Negative: As the independent variable (\(x\)) increases, the dependent variable (\(y\)) tends to decrease. The points trend downward.
Definition — Form: Linear or Non-linear
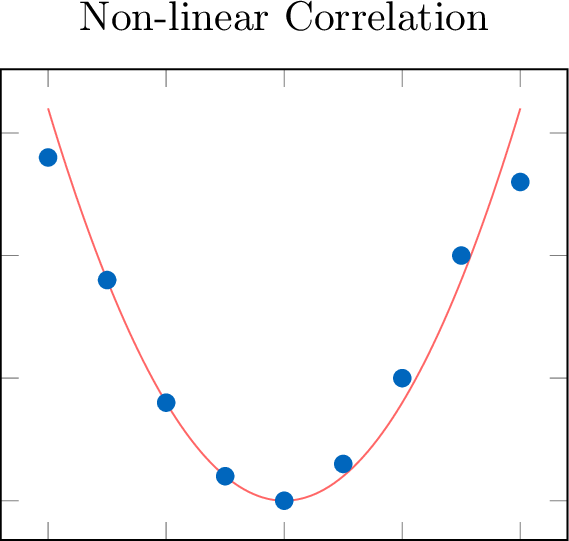
The form of the relationship is linear if the data points appear to follow a straight-line pattern. If they follow a curve other than a straight line, the form is non-linear. 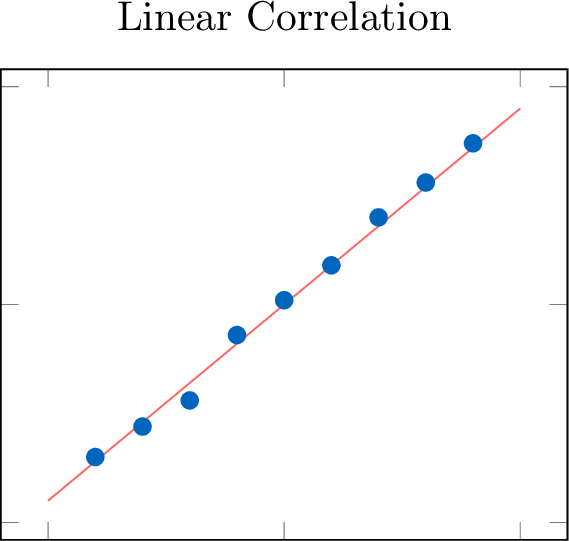
Definition — Strength
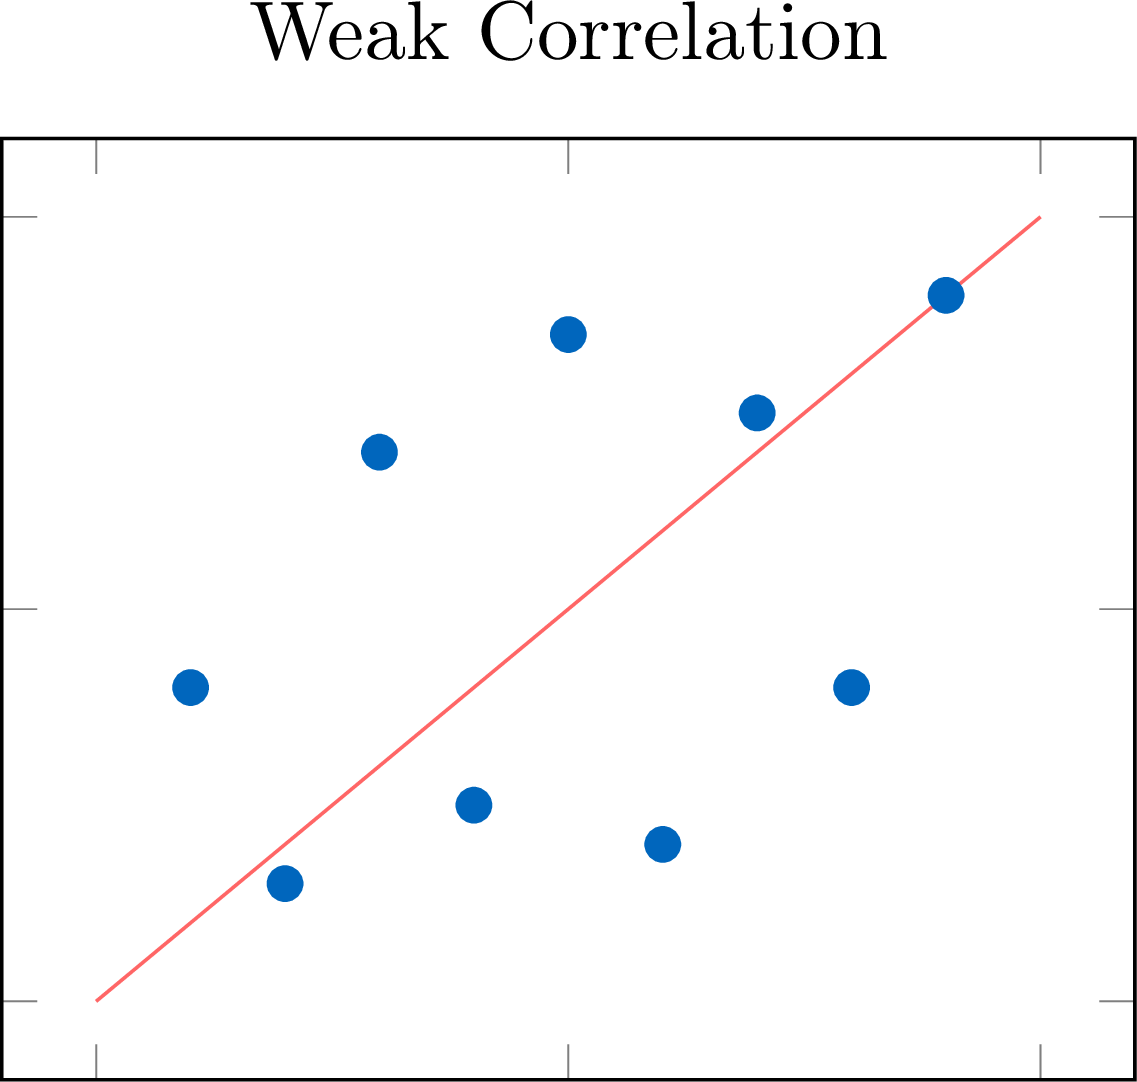
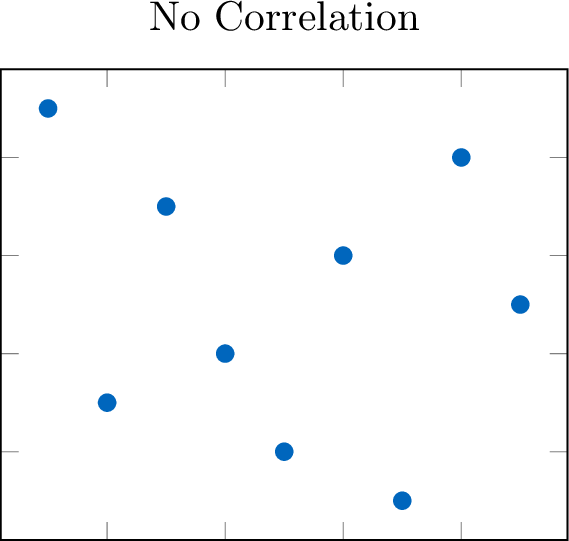
The strength of a correlation describes how closely the data points adhere to the identified form. 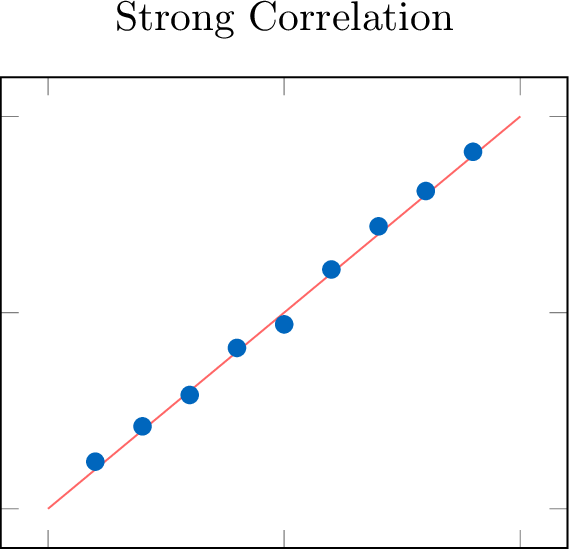
Definition — Outliers
An outlier is a data point that deviates significantly from the main pattern of the data. 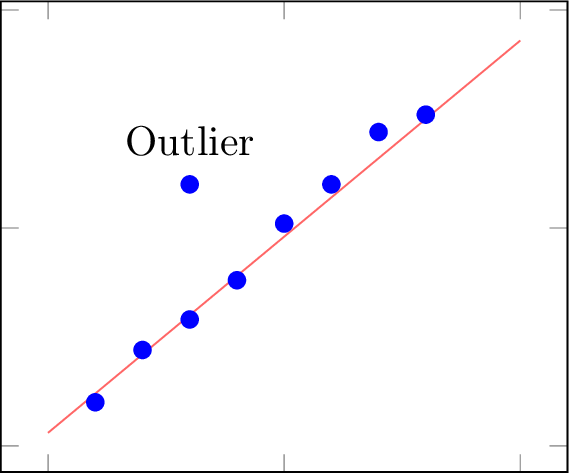
Method — Describing a Correlation
To describe the relationship shown in a scatter plot, we always comment on all four features in a concise statement. - Direction: Is the trend upward (positive), downward (negative), or neither?
- Form: Is it linear, non-linear, or without any clear form?
- Strength: Is it strong, moderate, or weak?
- Outliers: Are there any notable outliers?
Example
Describe the correlation between hours studied and exam scores shown in this scatter plot. 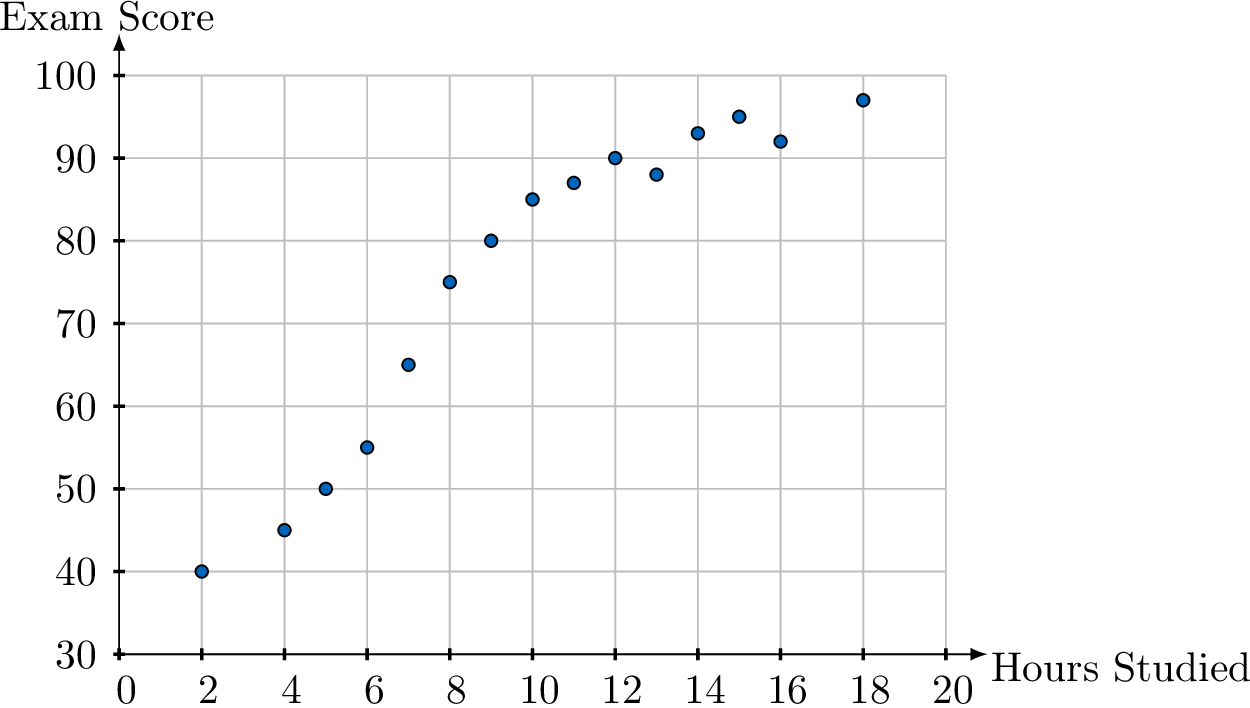
There is a strong, positive correlation between hours studied and exam scores: as the number of hours studied increases, the exam score tends to increase. Its form is not quite linear: the scores rise quickly up to about \(10\) hours, then level off, so the cloud bends. There are no obvious outliers.
Skills to practice
- Identifying the Strength of a Correlation
- Identifying the Form of a Correlation
- Plotting and Describing Scatter Diagrams
I.4
Correlation and Causation
Recappreviously studied — click to reread
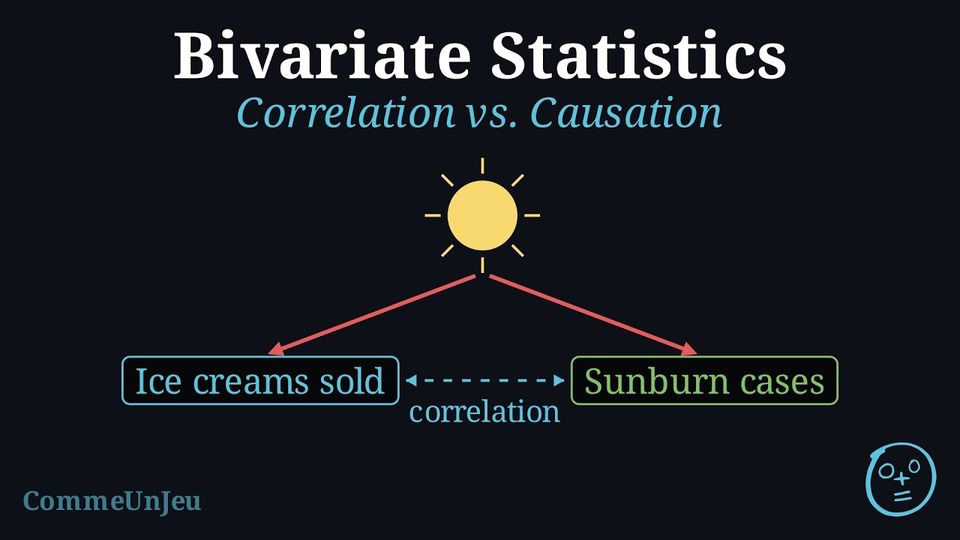
Correlation Does Not Imply Causation
Observing a statistical relationship (correlation) between two variables, \(x\) and \(y\), is not sufficient evidence to conclude that a change in \(x\) causes a change in \(y\).
Definition — Causation
Causation exists when a change in the independent variable produces — directly or through intermediate steps — a change in the dependent variable. The strongest evidence for causation comes from a carefully designed controlled experiment; observational data alone is rarely enough. Definition — Confounding Variable
Often, a correlation between two variables (\(x\) and \(y\)) is created or distorted by a third factor — observed or not — known as a confounding variable. This variable influences both \(x\) and \(y\), so that part or all of their correlation comes from it rather than from a direct link between \(x\) and \(y\). Example
Data shows a strong positive correlation between ice cream sales and the number of people who get sunburned.Does this mean eating ice cream causes sunburn? If not, identify the relationships and the likely confounding variable.
No, eating ice cream does not cause sunburn. 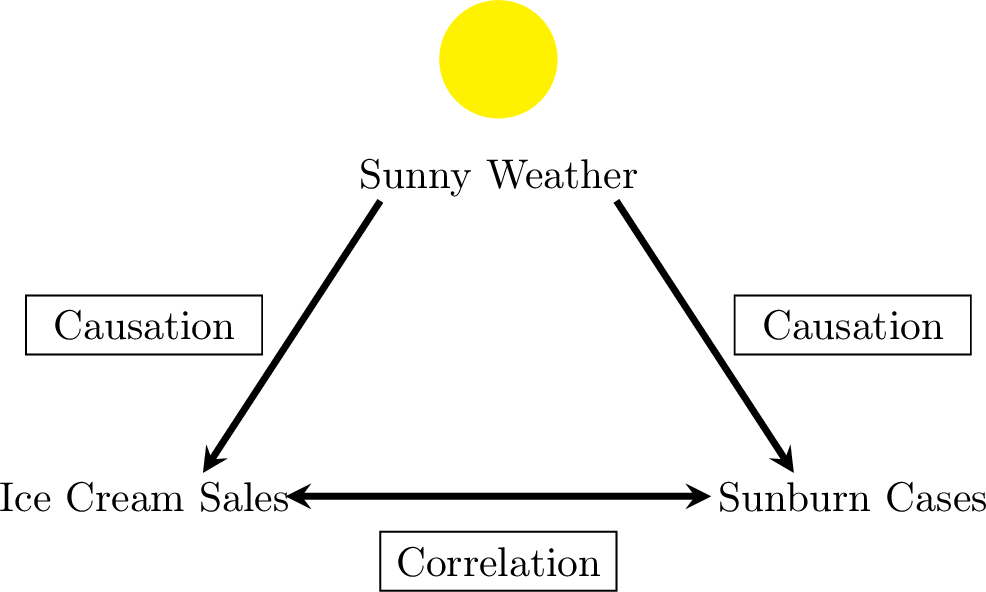
- The relationship between ice cream sales and sunburn cases is a correlation, not causation.
- The likely confounding variable is Sunny Weather. Hot and sunny days cause an increase in ice cream sales and also cause an increase in people getting sunburned.
Skills to practice
- Analysing Correlation and Causation
II
Measuring Correlation
II.1
Pearson's Correlation Coefficient
Recappreviously studied — click to reread
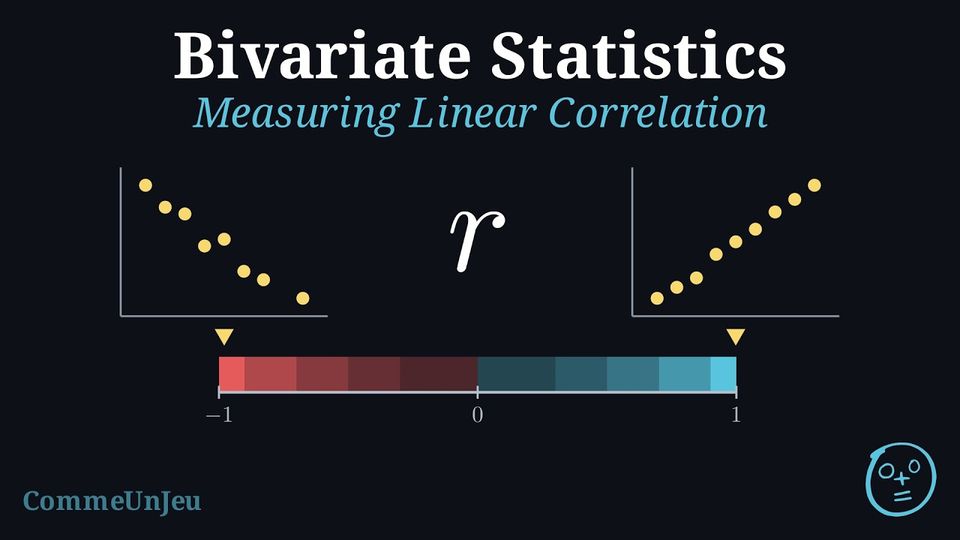
While scatter plots allow us to visually describe a correlation, this assessment is subjective. To provide a precise and objective measure of the strength and direction of a linear relationship, we use numerical coefficients.
Definition — Pearson's Correlation Coefficient (\(r\))
The Pearson's correlation coefficient (\(r\)) is a value in the range \([-1, 1]\) that quantifies the direction and strength of a linear relationship between two quantitative variables. - The sign of \(r\) indicates the direction (positive or negative).
- The magnitude (absolute value) of \(r\) indicates the strength. An \(|r|\) value close to 1 implies a strong linear correlation, while a value close to 0 implies a weak or no linear correlation.
| Value of \(|r|\) | Strength of Correlation |
| \(|r| = 1\) | Perfect |
| \(0.9 \le |r| < 1\) | Very Strong |
| \(0.7 \le |r| < 0.9\) | Strong |
| \(0.5 \le |r| < 0.7\) | Moderate |
| \(0.3 \le |r| < 0.5\) | Weak |
| \(0 \le |r| < 0.3\) | Very Weak or None |
Definition — Coefficient of Determination (\(r^2\))
The coefficient of determination (\(r^2\)) is the square of the correlation coefficient. It is a value in the range \([0, 1]\) and is typically expressed as a percentage.The value of \(r^2\) represents the proportion of the variance in the dependent variable (\(y\)) that is explained by the linear relationship with the independent variable (\(x\)). In simple terms, it tells us how well the linear model fits the data.
Method — Obtaining \(r\) and \(r^2\) with Technology
In this method, the correlation coefficient \(r\) is not computed by hand: a calculator or a spreadsheet gives it from the data, together with \(r^2\). - Enter the data: the values of \(x\) in one list (or one column), the values of \(y\) in another, in the same order, so that each pair stays on the same row.
- Ask for the two-variable statistics: on a calculator, the two-variable statistics menu gives \(r\) and \(r^2\); on many models they appear on the linear regression screen \(y = ax + b\), beside the coefficients \(a\) and \(b\) of the least squares line (on some models, the display of \(r\) and \(r^2\) must first be switched on in the settings, and some models show only \(r\)); in a spreadsheet, with \(x\) in
A2:A9and \(y\) inB2:B9, the formula=CORREL(A2:A9,B2:B9)gives \(r\) and=RSQ(B2:B9,A2:A9)gives \(r^2\). - Round only at the end: keep the full value on the screen and give \(r\) and \(r^2\) rounded, usually to three decimal places; \(r^2\) is the square of the unrounded \(r\), so when only \(r\) is displayed, square the full value of \(r\).
- Check with the scatter plot: the sign of \(r\) should agree with the general direction of the cloud, and \(|r|\) with how closely the points follow a line. When they disagree, check that each pair was entered on the same row, and look for an outlier, which can change \(r\) a lot.
Example
The coach of a running club records, for eight runners, the distance \(x\) run in training each week, in kilometres, and the time \(y\) of each runner in a \(5\) km race, in minutes. | \(x\) (km) | \(10\) | \(15\) | \(20\) | \(25\) | \(30\) | \(35\) | \(40\) | \(50\) |
| \(y\) (min) | \(31.5\) | \(30.2\) | \(29.8\) | \(27.9\) | \(28.3\) | \(26.4\) | \(25.9\) | \(24.8\) |
- Use technology to find \(r\) and \(r^2\), rounded to three decimal places.
- Describe the correlation between \(x\) and \(y\).
- Interpret \(r^2\) in the context.
- With the distances in L1 and the times in L2, the linear regression gives the screen below.
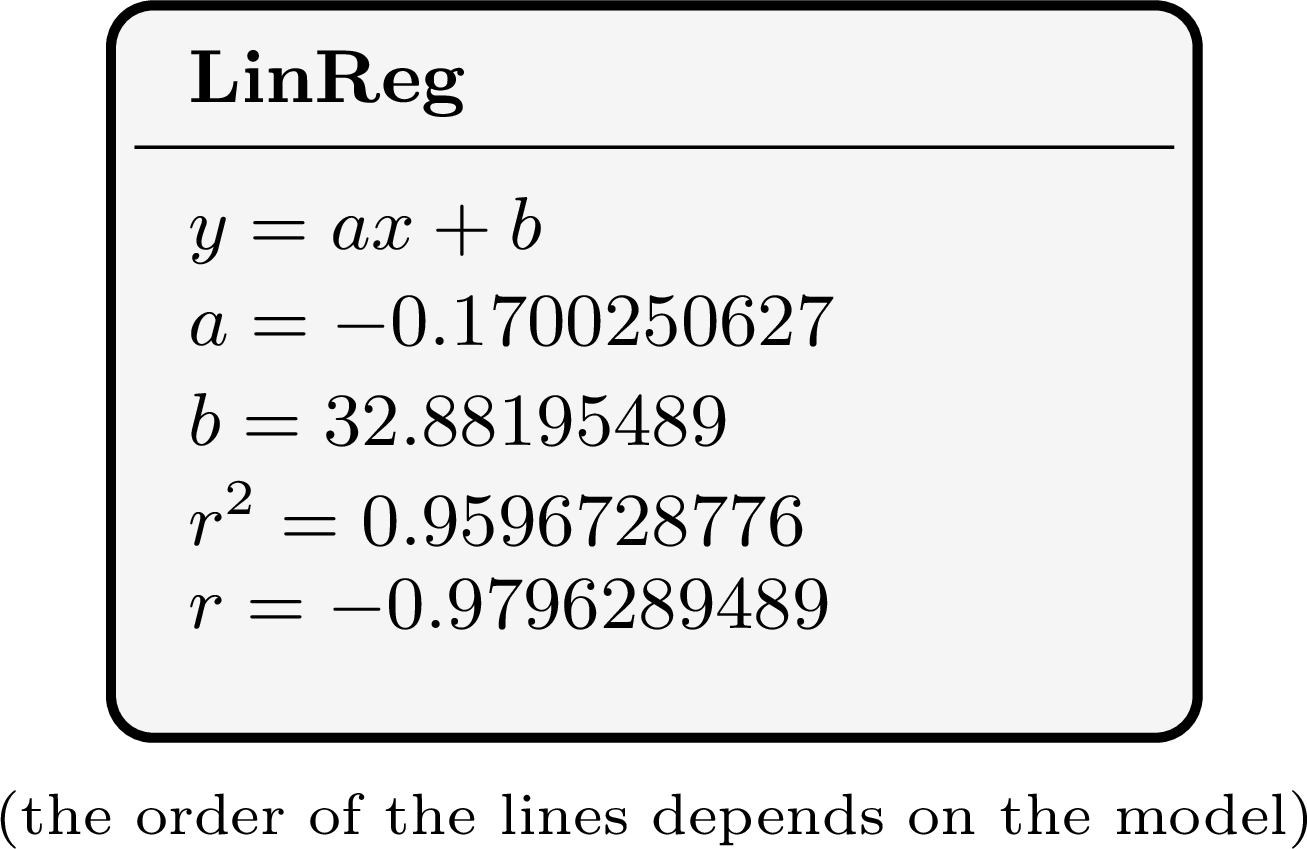
=CORREL(A2:A9,B2:B9)gives the same \(r\). - \(r\) is negative, so the correlation is negative: the runners who train more tend to have shorter race times. \(|r| \approx 0.980\) lies between \(0.9\) and \(1\), so the linear correlation is very strong. The sign agrees with the data: the times go down as the distances go up.
- \(r^2 \approx 0.960\): about \(96\pourcent\) of the variation in the race times is explained by the linear relationship with the training distance; the remaining \(4\pourcent\) is not explained by this linear relationship (other factors, measurement errors, natural variation). This is a correlation, not a proof that training alone makes the runners faster.
A correlation coefficient \(r\) is almost always computed from a sample, not from a whole population. Like any sample statistic, it is subject to sampling fluctuation: a different sample would give a slightly different \(r\). A strong \(r\) from a small sample is therefore weaker evidence of a real relationship than the same \(r\) from a large one — and deciding whether a whole population is genuinely correlated is itself a hypothesis test.
Skills to practice
- Estimating the Correlation Coefficient
- Computing the Correlation Coefficient with Technology
III
Lines of Best Fit
III.1
Line of Best Fit by Eye
Recappreviously studied — click to reread
Definition — Mean Point
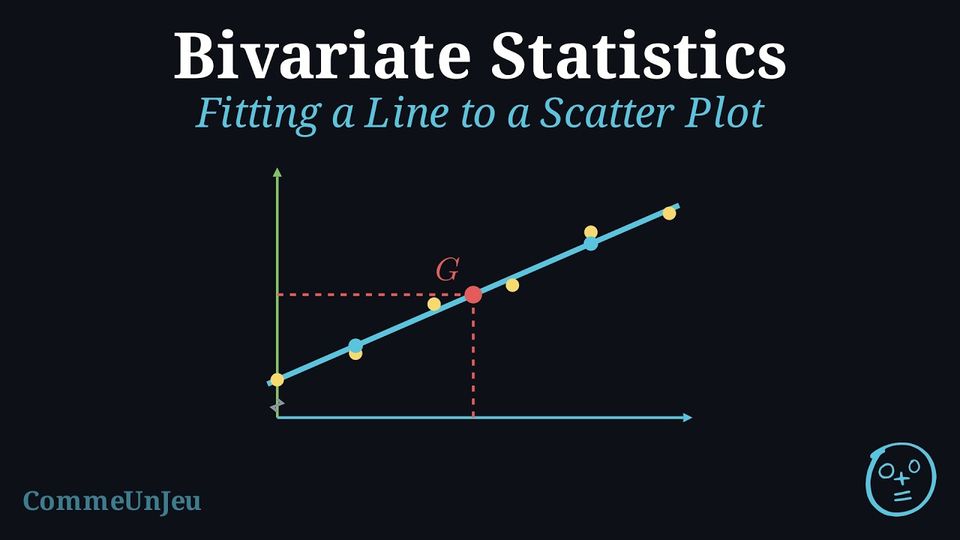
The mean point of a scatter plot with points \((x_1, y_1), (x_2, y_2), \ldots, (x_n, y_n)\) is the point \(G(\bar{x}, \bar{y})\) whose coordinates are the means of the two variables: $$\bar{x} = \frac{x_1 + x_2 + \cdots + x_n}{n} \qquad \text{and} \qquad \bar{y} = \frac{y_1 + y_2 + \cdots + y_n}{n}.$$ The mean point is the “centre of gravity” of the cloud: it is usually not one of the plotted points. Method — Fitting a Line by Eye
When the points of a scatter plot lie roughly along a straight line, one can fit a line to the cloud, that is, draw a line that follows the trend of the points: - Plot the mean point \(G\) and make the line pass through it.
- Follow the cloud: turn the line around \(G\) so that it follows the direction of the points, with all of them as close to it as possible — as a rough check, the points should be spread on both sides of the line.
- Read its equation \(y = ax + b\) on the graph (two points of the line give \(a\), then \(b\)).
Skills to practice
- Estimating the Line of Best Fit by Eye
III.2
The Least Squares Regression Line
Recappreviously studied — click to reread
Definition — Least Squares Regression Line
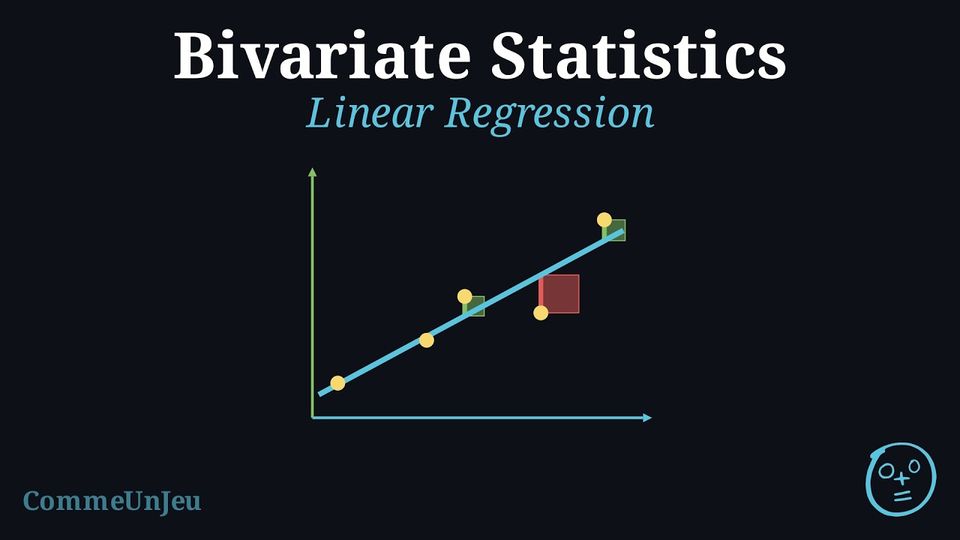
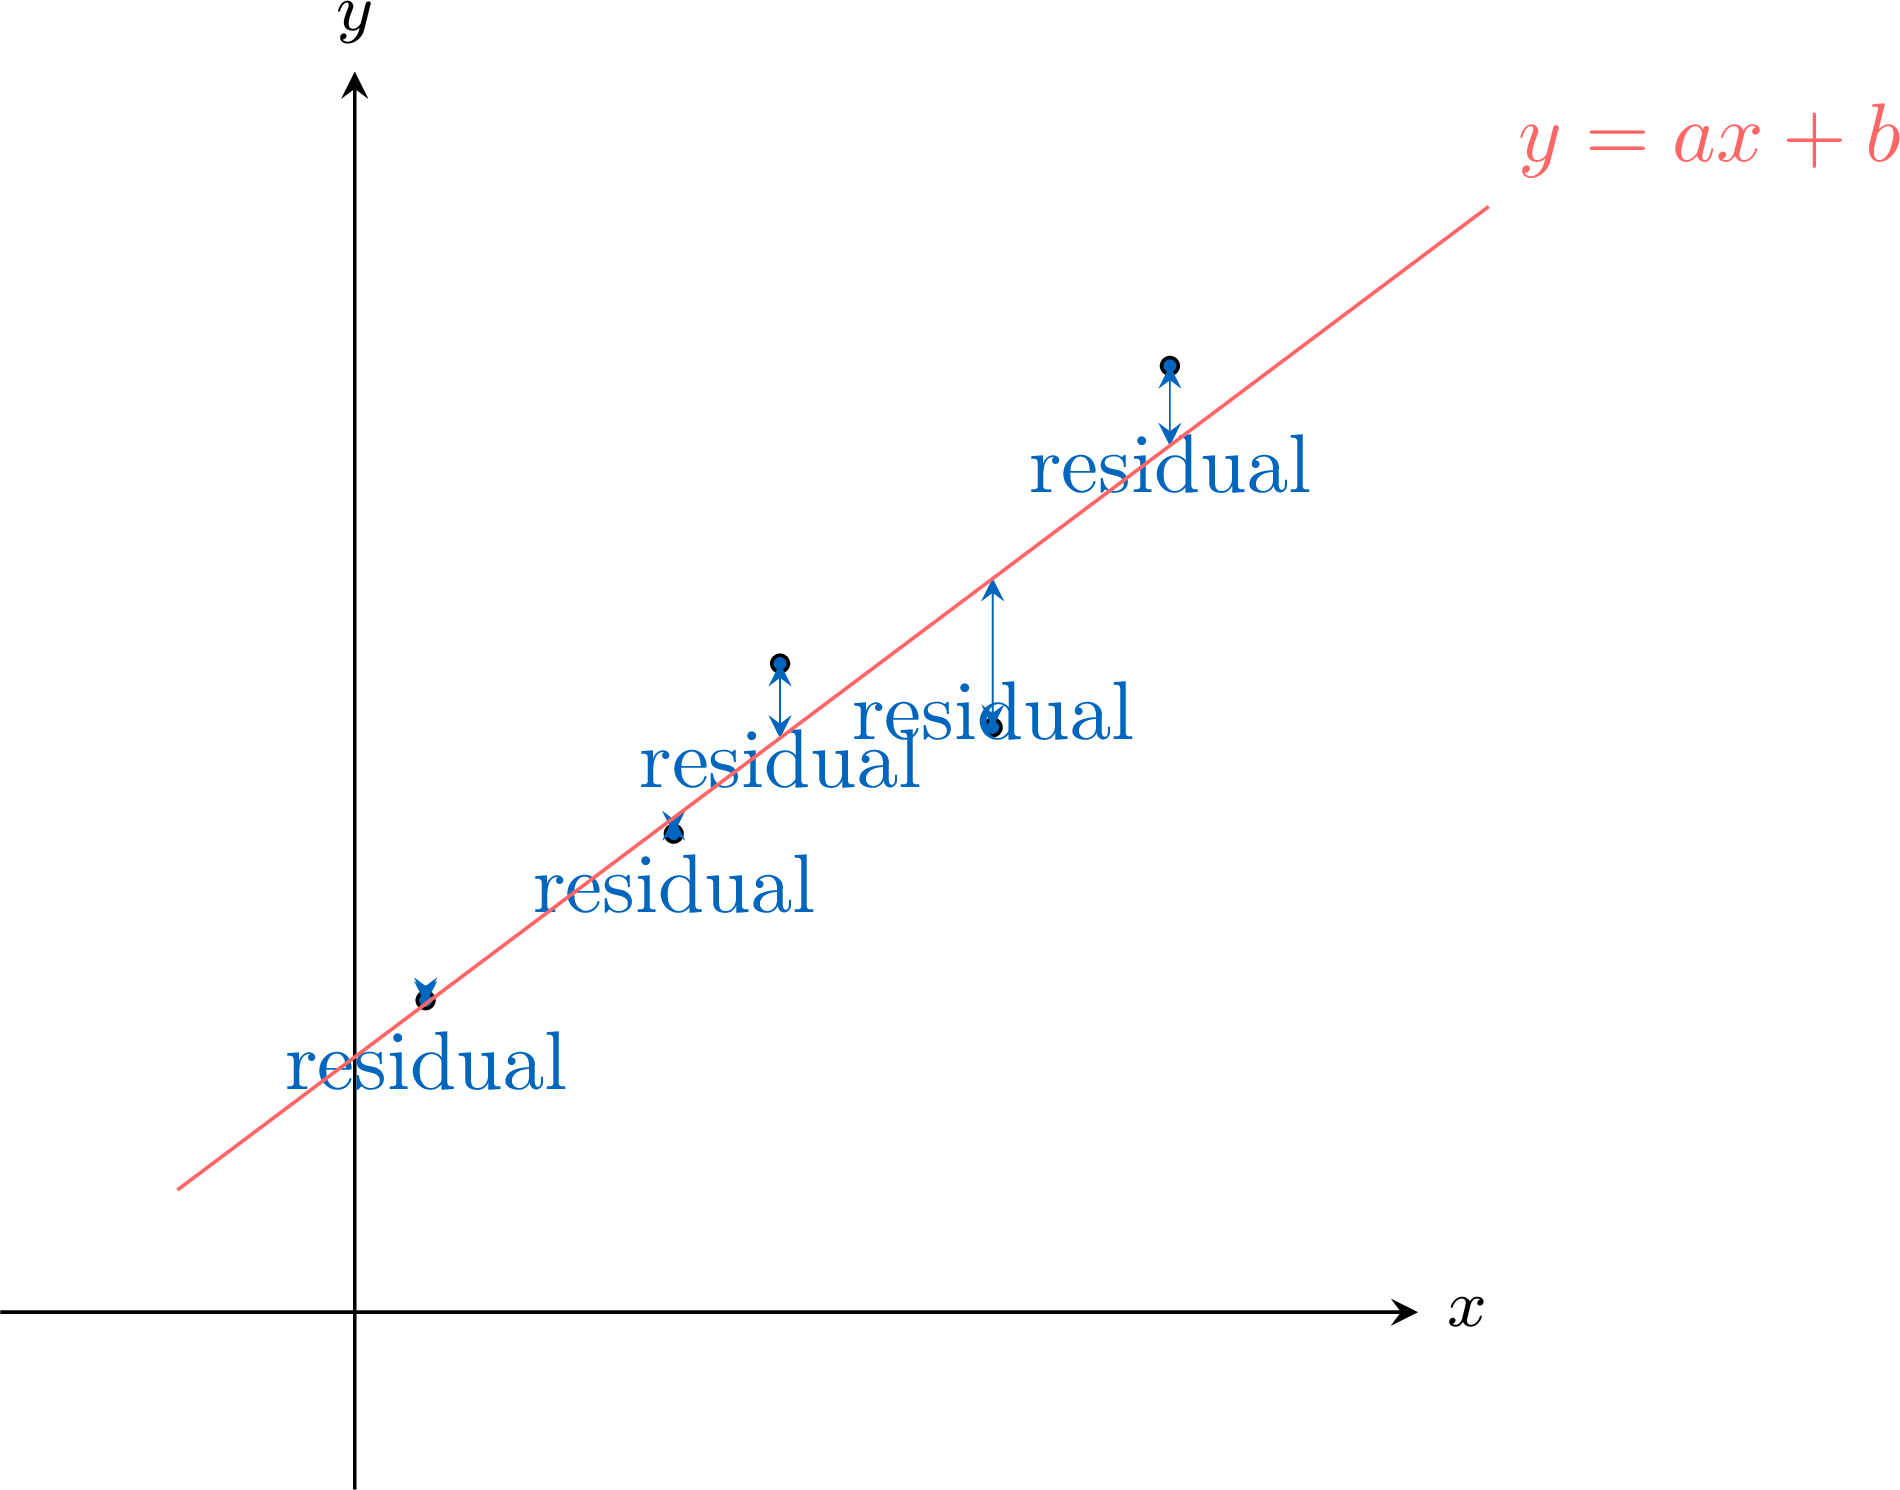
The least squares regression line, written as \(y = ax + b\), is the unique line of best fit (provided the \(x\)-values are not all equal) that models the linear relationship between \(x\) and \(y\). It is calculated by minimising the sum of the squares of the residuals.A residual is the signed vertical difference (positive above the line, negative below) between an observed data point \((x_i, y_i)\) and the predicted point on the regression line \((x_i, \hat{y}_i)\).$$ \text{Residual} = \text{observed } y - \text{predicted } y = y_i - \hat{y}_i $$ A key property is that the least squares regression line always passes through the mean point, \((\bar{x}, \bar{y})\).
Method — Obtaining the Least Squares Line with a Calculator or a Spreadsheet
The coefficients \(a\) and \(b\) of the least squares line \(y = ax + b\) are not computed by hand: a calculator or a spreadsheet gives them. - Enter the data: the values of \(x\) in one list (or one column), the values of \(y\) in another, in the same order.
- Ask for the line: on a calculator, the two-variable statistics menu, linear regression \(y = ax + b\); in a spreadsheet, with \(x\) in
A2:A6and \(y\) inB2:B6, the formulas=SLOPE(B2:B6,A2:A6)and=INTERCEPT(B2:B6,A2:A6), or a linear trend line added to the scatter plot, with its equation displayed. - Round sensibly: keep about as many significant figures as the measurements have, and write the equation with the letters of the situation.
- Check with the mean point: the least squares line passes through \(G(\bar{x}, \bar{y})\); replacing \(x\) by \(\bar{x}\) in the equation must give \(\bar{y}\), up to rounding.
Example
A laboratory prepares five solutions of known concentration \(x\), in milligrams per litre, and measures the absorbance \(y\) of each one. | \(x\) | \(2\) | \(4\) | \(6\) | \(8\) | \(10\) |
| \(y\) | \(0.11\) | \(0.19\) | \(0.31\) | \(0.40\) | \(0.49\) |
- Give, with a calculator, the equation of the least squares line, with \(a\) rounded to four decimal places and \(b\) to three.
- Check that this line passes through the mean point.
- Predict the absorbance of a solution of concentration \(7\) mg/L.
- A sample of unknown concentration has an absorbance of \(0.35\). Here the measured value is \(y\): use the same equation the other way round to estimate its concentration.
- The calculator gives \(a = 0.0485\) and \(b = 0.009\): the calibration line is \(y = 0.0485x + 0.009\) (the gradient is kept with three significant figures).
- \(\bar{x} = 6\) and \(\bar{y} = 0.30\). For \(x = 6\) the equation gives \(0.0485 \times 6 + 0.009 = 0.300\): the line passes through \(G(6, 0.30)\).
- \(0.0485 \times 7 + 0.009 = 0.3485\): the expected absorbance is about \(0.35\).
- Solve \(0.0485x + 0.009 = 0.35\): \(x = \dfrac{0.35 - 0.009}{0.0485} \approx 7.0\). The concentration is about \(7.0\) mg/L. This value lies between \(2\) and \(10\) mg/L, the smallest and the largest concentrations measured: the line is used inside the range where it was fitted.
Definition — Interpolation and Extrapolation
The line of best fit can be used to make predictions: - Interpolation is the process of predicting a \(y\)-value for an \(x\)-value that is within the range of the original data. If the correlation is strong, interpolation is generally considered reliable (provided the linear model fits the data well).
- Extrapolation is the process of predicting a \(y\)-value for an \(x\)-value that is outside the range of the original data. Extrapolation is generally considered unreliable, as we cannot assume the linear trend continues indefinitely.
Example
For a survey of hours studied and exam scores (out of \(100\)), a calculator gives the line of best fit \(y = 3.5x + 40\). In this dataset, the hours studied ranged from 2 to 15. - Predict the exam score for a student who studied for 11 hours.
- Predict the exam score for a student who studied for 25 hours.
- Comment on the reliability of the prediction in question 2.
- Since \(x=11\) is within the data range, this is interpolation. $$ y = 3.5(11) + 40 = 38.5 + 40 = 78.5 $$ The predicted score is 78.5.
- Since \(x=25\) is outside the data range, this is extrapolation. $$ y = 3.5(25) + 40 = 87.5 + 40 = 127.5 $$ The predicted score is 127.5.
- The prediction in question 2 is unreliable. It is an extrapolation, and we cannot assume the linear relationship holds for 25 hours of study. Furthermore, the model predicts a score over 100, which is impossible in this context, highlighting the danger of extrapolation.
Example
The average weekly study time and the final mathematics test score for a selection of students are shown below: | Study Time (\(x\) hours) | 2 | 5 | 1 | 7 | 4 | 9 | 6 | 3 |
| Test Score (\(y\) marks) | 45 | 65 | 30 | 85 | 60 | 95 | 70 | 55 |
- Construct a scatter diagram to illustrate the data.
- Find the equation of the regression line \(y\) on \(x\). State and interpret its gradient in the context of the problem.
- Estimate the test score for a student who studies for 8 hours per week.
- Explain why the regression line of \(y\) on \(x\) should not be used to estimate the weekly study time of a student who scores 40 marks.
- Comment on the reliability of your estimate in 3, and say whether the score of 40 marks in 4 lies within the range of the data.
- Scatter Diagram:
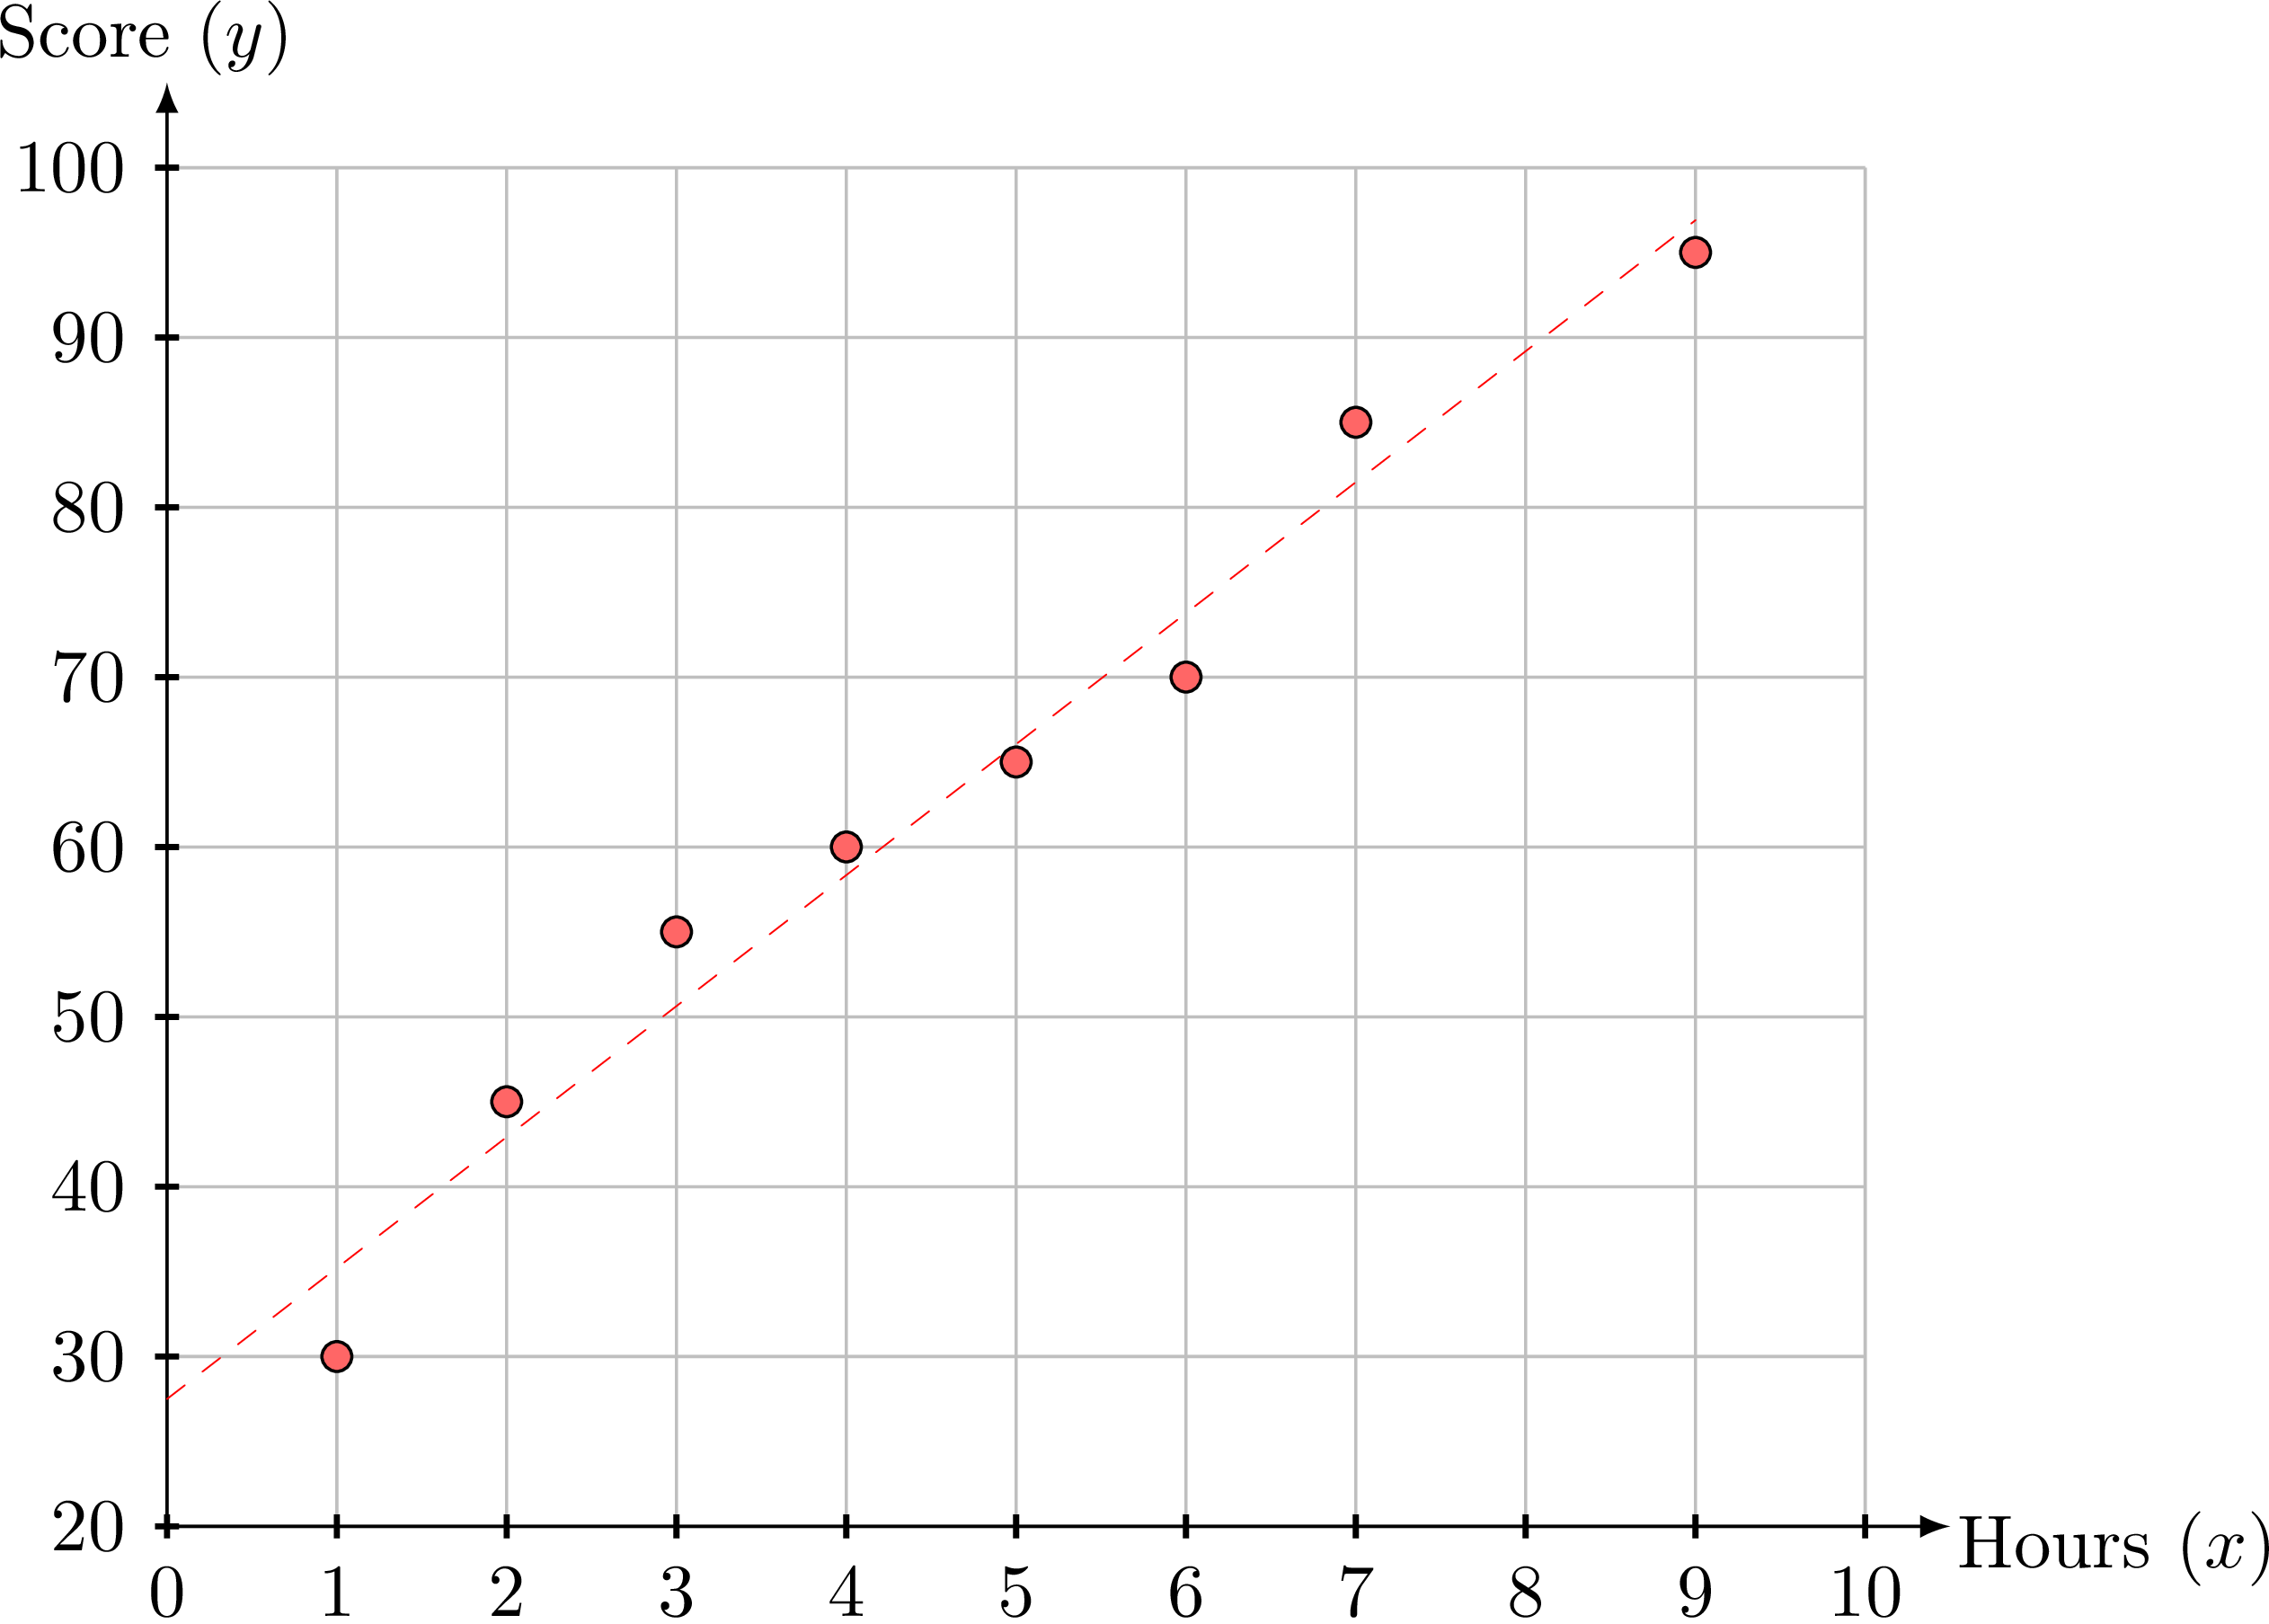
- Regression Line:
Using a calculator, the equation is approximately: $$y = 7.71x + 27.5$$ Interpretation:
The gradient is \(7.71\). This means that for every additional hour spent studying per week, the test score increases by approximately 7.7 marks on average. - Estimation (Score for 8 hours):
Substitute \(x = 8\) into the equation: $$y = 7.71(8) + 27.5 = 89.2$$ The estimated score is roughly 89 marks. - Predicting in the Other Direction (40 marks):
Here the study time \(x\) would be estimated from a given score \(y = 40\). The line of \(y\) on \(x\) is built to estimate \(y\) from \(x\): it makes the sum of the squares of the vertical distances between the points and the line as small as possible. Estimating \(x\) from \(y\) would require the horizontal distances to be small, and solving \(y = 7.71x + 27.5\) for \(x\) does not give the line that achieves this. A regression line of \(y\) on \(x\) does not reliably predict \(x\) from \(y\). - Reliability:
- The estimate in 3 (\(x=8\)) is reliable because 8 hours is within the range of the given data (\(1 \le x \le 9\)). This is interpolation.
- The score \(y = 40\) in 4 lies within the observed scores (\(30 \le y \le 95\)): an estimate of the study time for this score would not be an extrapolation. What rules out the line of \(y\) on \(x\) in 4 is the direction of the prediction, not the range of the data.
Skills to practice
- Comparing Lines with the Sum of the Squares
- Fitting a Line in Context with a Calculator
IV
Spearman's Rank Correlation
IV.1
Spearman's Rank Correlation Coefficient
When the Trend Is Not a Line
Pearson's coefficient \(r\) measures how closely the points of a scatter diagram follow a line. Many relationships go steadily up, or steadily down, without following a line: a plant grows quickly and then more and more slowly; a medicine leaves the blood quickly and then slowly. For such data, \(r\) underestimates how regular the relationship is. Spearman's idea is to forget the values and to keep only their order: which value is the smallest, which is the second smallest, and so on.
Definition — Ranks and Ties
To rank a list of \(n\) values, order them from the smallest to the largest: the smallest value has rank \(1\), the next one rank \(2\), and so on up to rank \(n\). Equal values are called ties; each of them receives the mean of the ranks that they occupy together.For instance, in the list \(12, 15, 15, 18\), the two values \(15\) occupy the ranks \(2\) and \(3\), so each receives the rank \(\frac{2 + 3}{2} = 2.5\): the ranks are \(1, 2.5, 2.5, 4\).
Definition — Spearman's Rank Correlation Coefficient
Let \((x_1, y_1), (x_2, y_2), \ldots, (x_n, y_n)\) be bivariate data. Rank the \(x\)-values among themselves, and the \(y\)-values among themselves (neither variable being constant). Spearman's rank correlation coefficient, written \(r_s\), is Pearson's correlation coefficient of the ranks: each pair \((x_i, y_i)\) is replaced by the pair (rank of \(x_i\), rank of \(y_i\)), and \(r\) is calculated for these new pairs.A relationship between \(x\) and \(y\) is monotonic when, as \(x\) increases, \(y\) never goes down (an increasing relationship), or never goes up (a decreasing relationship). To tell the two coefficients apart, Pearson's coefficient is sometimes written \(r_p\).
Proposition — Reading Spearman's Coefficient
- Like any Pearson coefficient, \(-1 \le r_s \le 1\).
- For data without ties, \(r_s = 1\) exactly when the ranks of \(y\) are the ranks of \(x\), that is when \(y\) increases every time \(x\) increases; \(r_s = -1\) exactly when \(y\) decreases every time \(x\) increases.
- The sign of \(r_s\) gives the direction of the trend (increasing or decreasing), and \(|r_s|\) close to \(1\) means a strong monotonic relationship. The scale of strength used for \(r\) is used for \(r_s\) in the same way.
- \(r_s\) says nothing about linearity: \(r_s = 1\) for points that rise along a curve.
Proposition — Spearman's Formula without Ties
When no two \(x\)-values are equal and no two \(y\)-values are equal, $$r_s = 1 - \frac{6\sum d^2}{n(n^2 - 1)},$$ where \(n\) is the number of pairs and \(d\) is, for each pair, the difference between the rank of \(x\) and the rank of \(y\). When there are ties, this formula is no longer valid in general, and its error can be large: \(r_s\) is then calculated as Pearson's coefficient of the ranks, with technology. Method — Calculating Spearman's Coefficient
- Rank each variable separately: the \(x\)-values among themselves, the \(y\)-values among themselves, from the smallest (rank \(1\)), giving tied values the mean of their ranks.
- With technology: enter the ranks of \(x\) and the ranks of \(y\) in two lists and ask for \(r\), as for any bivariate data: the value displayed is \(r_s\). In a spreadsheet,
=RANK.AVG(A2,A2:A9,1)gives the rank of the value inA2among the values ofA2:A9, ties averaged (fix the range before copying the formula down);=CORRELapplied to the two columns of ranks then gives \(r_s\). Some calculators and software give \(r_s\) directly. - By hand, when there are no ties: write the difference \(d\) of the two ranks for each pair, then \(\sum d^2\), and apply Spearman's formula.
- Interpret: state the direction and the strength of the monotonic trend, in the words of the context.
Example
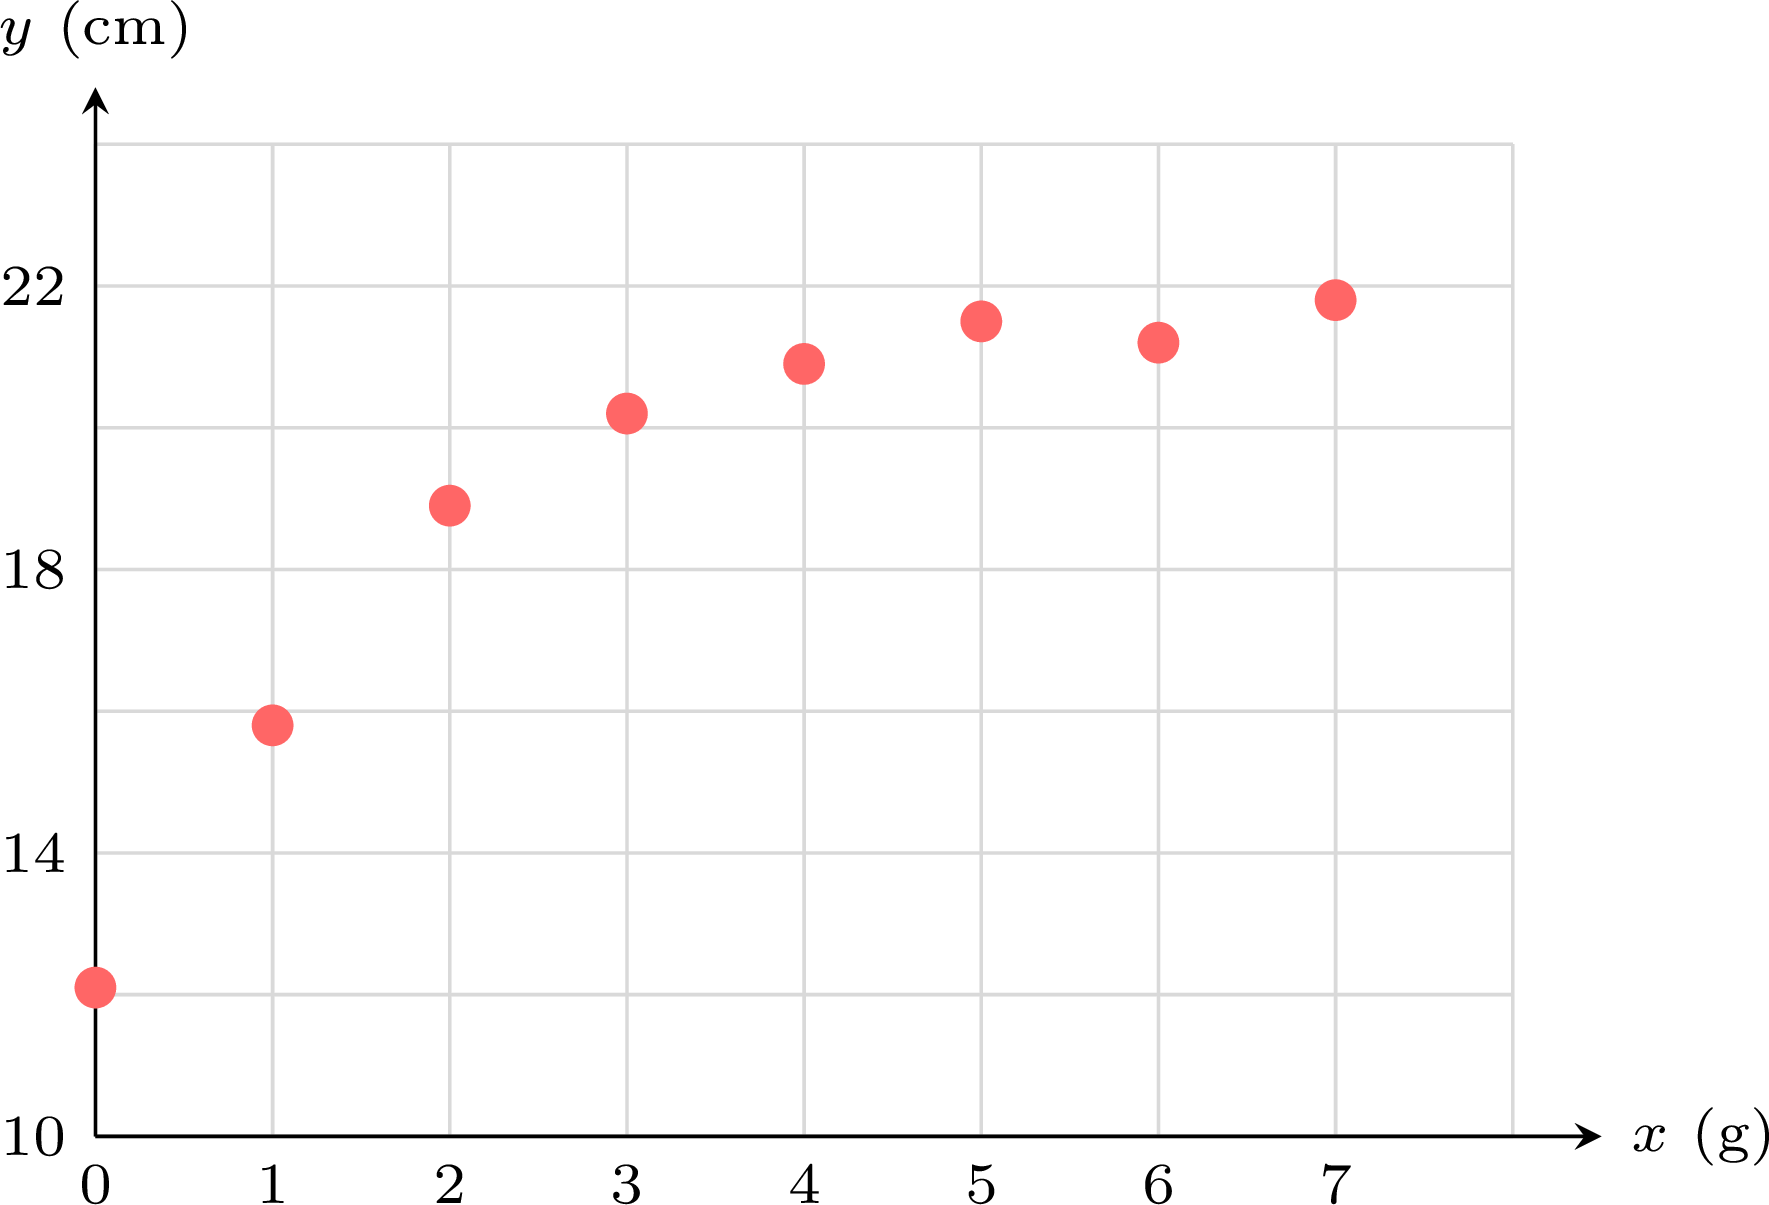
Eight identical seedlings receive different amounts \(x\) of fertiliser, in grams; their height \(y\), in centimetres, is measured four weeks later. | \(x\) (g) | \(0\) | \(1\) | \(2\) | \(3\) | \(4\) | \(5\) | \(6\) | \(7\) |
| \(y\) (cm) | \(12.1\) | \(15.8\) | \(18.9\) | \(20.2\) | \(20.9\) | \(21.5\) | \(21.2\) | \(21.8\) |
- Draw the scatter diagram and use technology to find Pearson's coefficient \(r\).
- Rank each variable and calculate Spearman's coefficient \(r_s\).
- Which coefficient describes this relationship better? Describe the correlation.
- The points rise quickly, then flatten out:
- The values of \(x\) are already in increasing order, so their ranks are \(1\) to \(8\). The heights ordered from the smallest are \(12.1, 15.8, 18.9, 20.2, 20.9, 21.2, 21.5, 21.8\), so \(21.2\) has rank \(6\) and \(21.5\) rank \(7\):
rank of \(x\) \(1\) \(2\) \(3\) \(4\) \(5\) \(6\) \(7\) \(8\) rank of \(y\) \(1\) \(2\) \(3\) \(4\) \(5\) \(7\) \(6\) \(8\) \(d\) \(0\) \(0\) \(0\) \(0\) \(0\) \(-1\) \(1\) \(0\) - The height rises quickly for the first grams of fertiliser, then much more slowly from \(3\) g on, with even a slight drop between \(5\) g and \(6\) g: the cloud bends, it does not follow a line. Apart from this one pair, the order of the heights is the order of the doses, which \(r_s \approx 0.976\) expresses, while \(r \approx 0.882\) is lower, mainly because the points are not on a line. Spearman's coefficient is the appropriate one: there is a very strong increasing trend between the amount of fertiliser and the height, and it is not linear.
Method — Choosing between \(r\) and \(r_s\)
- Look at the scatter diagram first: a coefficient summarises a cloud, it never replaces it.
- Points close to a line: Pearson's \(r\) measures the strength of the linear relationship; it is the coefficient that goes with the least squares line.
- Points rising or falling steadily along a curve, or data that are ranks (positions in a competition, preferences, marks given by judges): Spearman's \(r_s\) measures the strength of the monotonic relationship.
- Beware of outliers: a single point far from the others can create or hide a linear correlation, so \(r\) is very sensitive to outliers. In the ranks, however far a point is, its rank is at most \(n\) or at least \(1\): its influence is bounded, so \(r_s\) is usually less sensitive, although moving one point can still shift several ranks. An outlier is not removed because it is far: only when it is an error, or when it does not belong to the population studied.
- Points that rise and then fall (or the reverse): neither coefficient describes the turning point; when the rise and the fall balance, both can be close to \(0\) while the points follow a clear pattern. Describe the shape of the cloud instead.
Example
Ten pupils note the number of hours \(x\) that they revised during the week before a test, and their mark \(y\) out of \(20\). | \(x\) | \(2\) | \(2.5\) | \(3\) | \(3.5\) | \(4\) | \(4.5\) | \(5\) | \(5.5\) | \(6\) | \(40\) |
| \(y\) | \(12\) | \(14\) | \(11\) | \(13\) | \(15\) | \(12\) | \(16\) | \(13\) | \(14\) | \(19\) |
- Rank the marks.
- Use technology to find \(r\) and \(r_s\).
- The value \(40\) hours is a recording error, and the true value is unknown. Remove this pupil, then find \(r\) and \(r_s\) again.
- Which coefficient did the error change more? Explain why.
- Ordered, the marks are \(11, 12, 12, 13, 13, 14, 14, 15, 16, 19\). The two \(12\)s share the ranks \(2\) and \(3\), so each has rank \(2.5\); likewise the \(13\)s have rank \(4.5\) and the \(14\)s rank \(6.5\):
\(y\) \(12\) \(14\) \(11\) \(13\) \(15\) \(12\) \(16\) \(13\) \(14\) \(19\) rank \(2.5\) \(6.5\) \(1\) \(4.5\) \(8\) \(2.5\) \(9\) \(4.5\) \(6.5\) \(10\) - The linear regression on \(x\) and \(y\) gives \(r = 0.7929\ldots \approx 0.793\). The values of \(x\) are all different and already in increasing order, so their ranks are \(1\) to \(10\); Pearson's coefficient of the ranks of \(x\) and the ranks of \(y\) gives \(r_s = 0.5688\ldots \approx 0.569\). There are ties, so Spearman's formula is not exact here.
- Without the tenth pupil, technology gives \(r = 0.4041\ldots \approx 0.404\) and \(r_s = 0.4050\ldots \approx 0.405\).
- The error moved \(r\) from \(0.404\) to \(0.793\): this single point almost doubled \(r\) and suggested a strong linear correlation that the other nine pupils do not show. It moved \(r_s\) from \(0.405\) to \(0.569\), much less. In the values, the point \((40, 19)\) lies \(34\) hours beyond all the others:
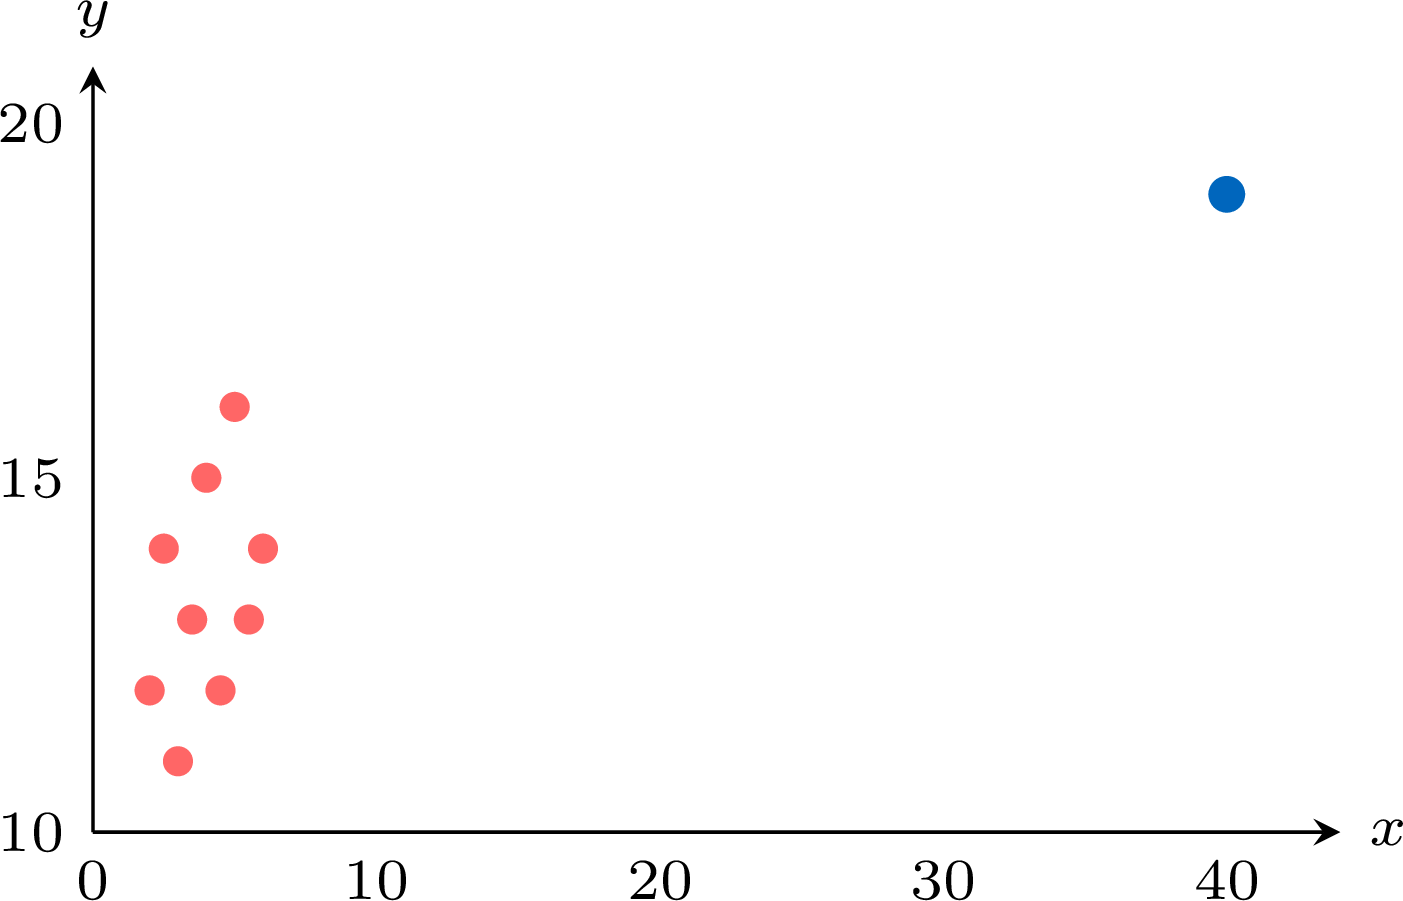
Skills to practice
- Choosing a Correlation Coefficient
- Calculating Spearman's Coefficient
- Comparing Pearson's and Spearman's Coefficients in Context
V
Going further
Skills to practice
- Solving Problems on Correlation and Regression
- Quiz
Jump to section